Skip to content

Multihull

Deploy hot GPU containers to many providers. One URL. Automatic failover.
Per-request failover across three providersRequests from one URL on the left reach the router ahead of the hulls, cross the forward beam and flow to the Kubernetes hull. Its circuit opens, the status pill turns coral and the stream moves to Modal within one beat while the error counter stays at zero. Modal's circuit opens too, its pill turns coral and the stream moves to RunPod; the error counter still reads zero and the failover counter reads two. Modal recovers through an amber half-open ramp and traffic climbs back to it, then Kubernetes recovers the same way and traffic returns to priority 1. With reduced motion the picture holds the frame where Kubernetes and Modal are both down and RunPod serves every request.llama-8bservingdownrecoveringllama.api.acme.comone URL0 errorsfailovers 0failovers 1failovers 2P1Kubernetes2 x L4servingdownrecoveringP2Modal1 x A10GservingdownrecoveringP3RunPod1 x L4servingrouterAll hulls serving. Requests flow to priority 1.Kubernetes circuit opens. Next request lands on Modal. Callers see zero errors.Modal circuit opens too. Requests land on RunPod. Still zero errors.Modal half-open: admit 1 request, then 5%, 25%, 100%.Modal recovered. Traffic climbs to priority 2. Kubernetes half-open.Recovered. Traffic returns to priority 1.
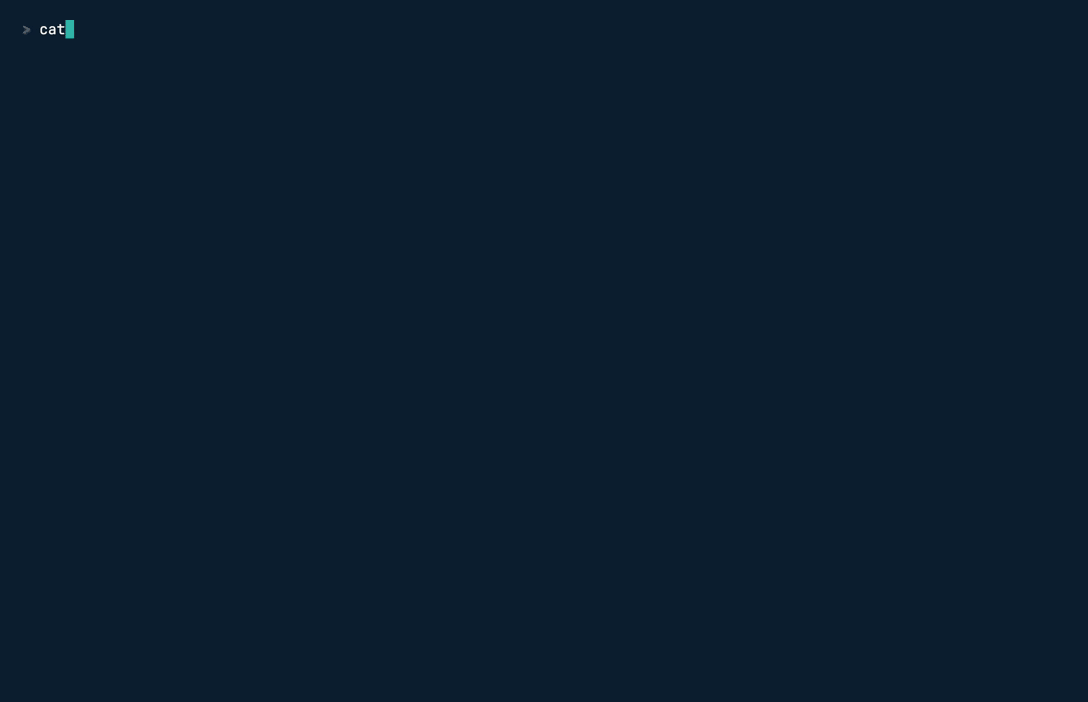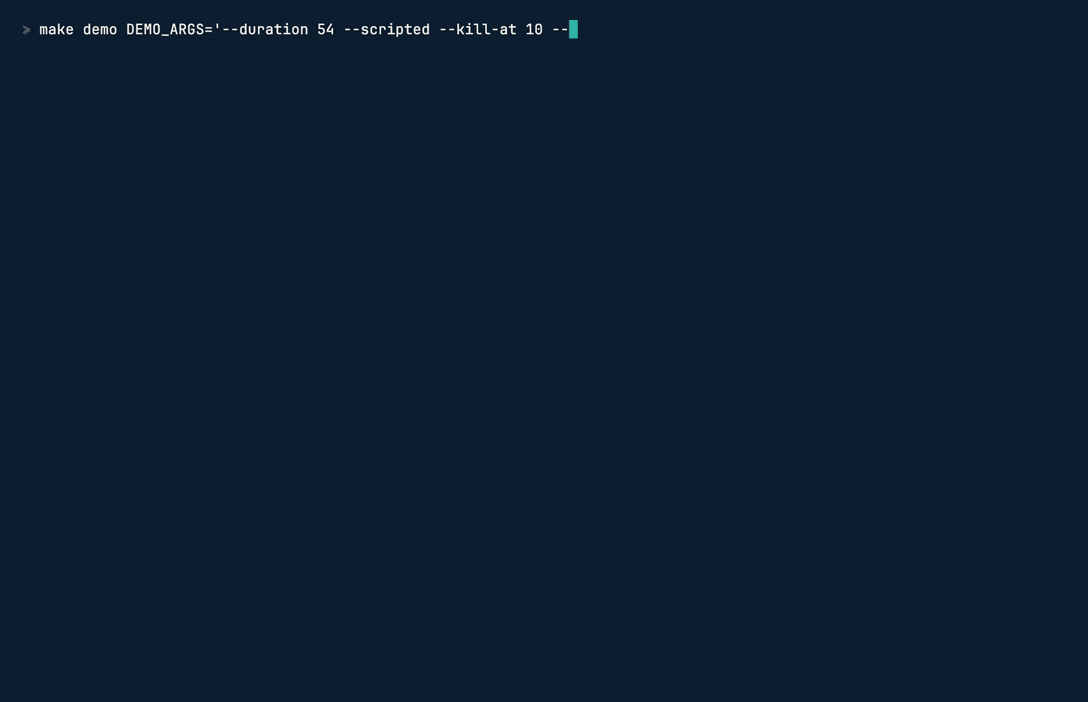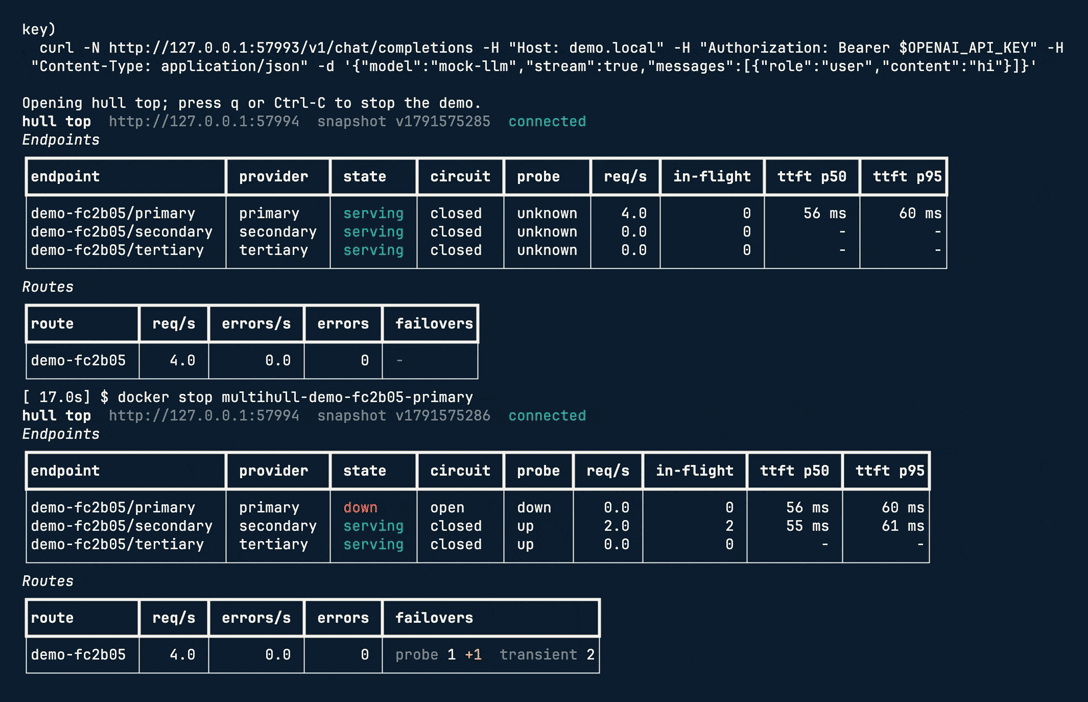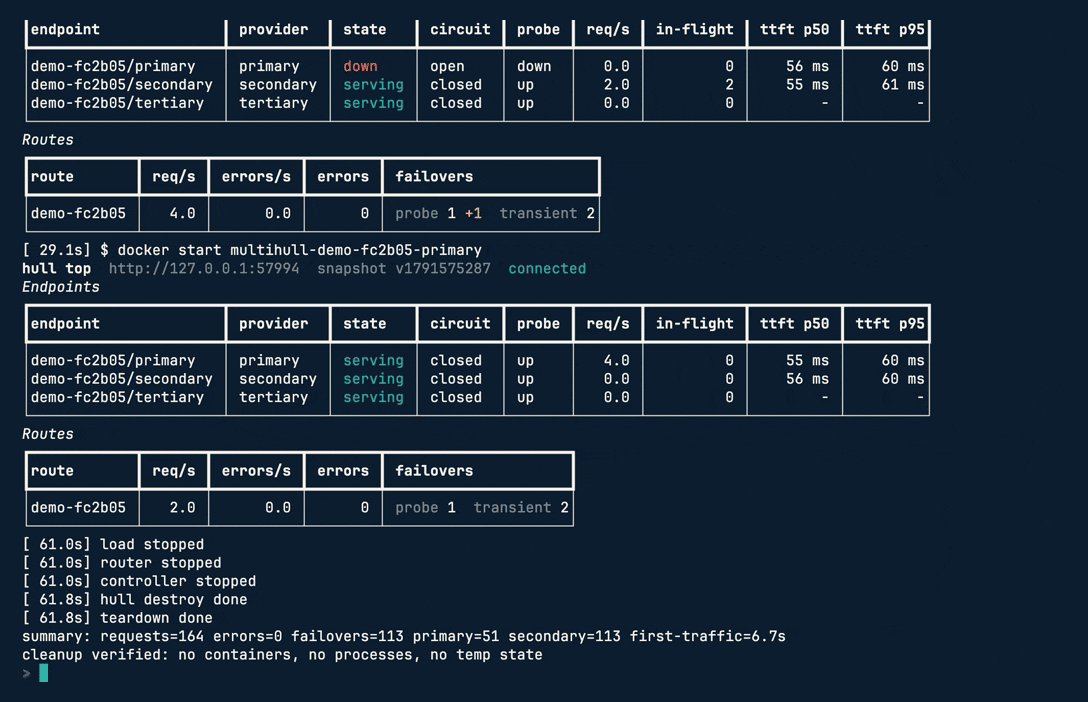
Terminal recording of make demo: the spec with three docker targets, hull deploy, streaming completions through one URL, hull top live, the primary stopped while traffic moves to the secondary with errors at 0, the primary restored and traffic returning to it

make demo in five beats: one spec and hull deploy; streaming completions through one URL; hull top live; the primary stopped, traffic moves, errors stay at 0; the primary restored, traffic returns. Free and local: examples/demo.

One spec

Image, GPU class, scaling and targets in one multihull.yaml. Each provider gets its native payload.

Always warm

Two providers stay hot by default. Fallbacks never scale to zero. Health beats price.

Per-request failover

A stateless Rust router retries across providers before the first byte. Callers see one URL.

Multihull in 23 seconds. The numbers come from the 0.2.0 cloud demo.


Two targets, one hostname. The control plane turns this into a Kubernetes Deployment and a Modal app. In 0.2.0 these two providers deploy and fail over; RunPod, Baseten and Replicate deploy on main, unreleased.

multihull.yaml
apiVersion: multihull/v1
name: llama-8b
container:
image: ghcr.io/acme/vllm-llama:1.4.0
port: 8000
health: {path: /health}
resources:
gpu: [L4, A10G]
targets:
- provider: gke-prod
type: kubernetes
priority: 1
- provider: modal-main
type: modal
priority: 2
route:
hostname: llama.api.acme.com
protocol: openai
One spec, five native payloadsThe spec file on the left connects to five translator boxes in the middle. Each translator points to an abstract provider glyph on the right with the native payload name under it.one spectranslatorsnative payloadsmultihull.yamlname: llama-8bcontainer:  image: ghcr.io/acme/vllmresources:  gpu: [L4, A10G]targets: 5kubernetesKubernetesDeploymentmodalModalmodal.ApprunpodRunPodEndpointbasetenBasetenTrussreplicateReplicateDeployment
One spec. One translator per provider. Native payloads, no shims.

The router owns liveness. The CLI prints what it sees. Three targets shown for the three states; 0.2.0 deploys Kubernetes and Modal.

Target State Replicas GPU
gke-prod Ready 2/2 L4
modal-main Degraded 1/1 A10G
runpod-eu Serving failover 1/1 L4